AI Data Licensing
The Ghost in Cold Storage: Why the Most Valuable Asset Your Closed Startup Left Behind Is Not the Code
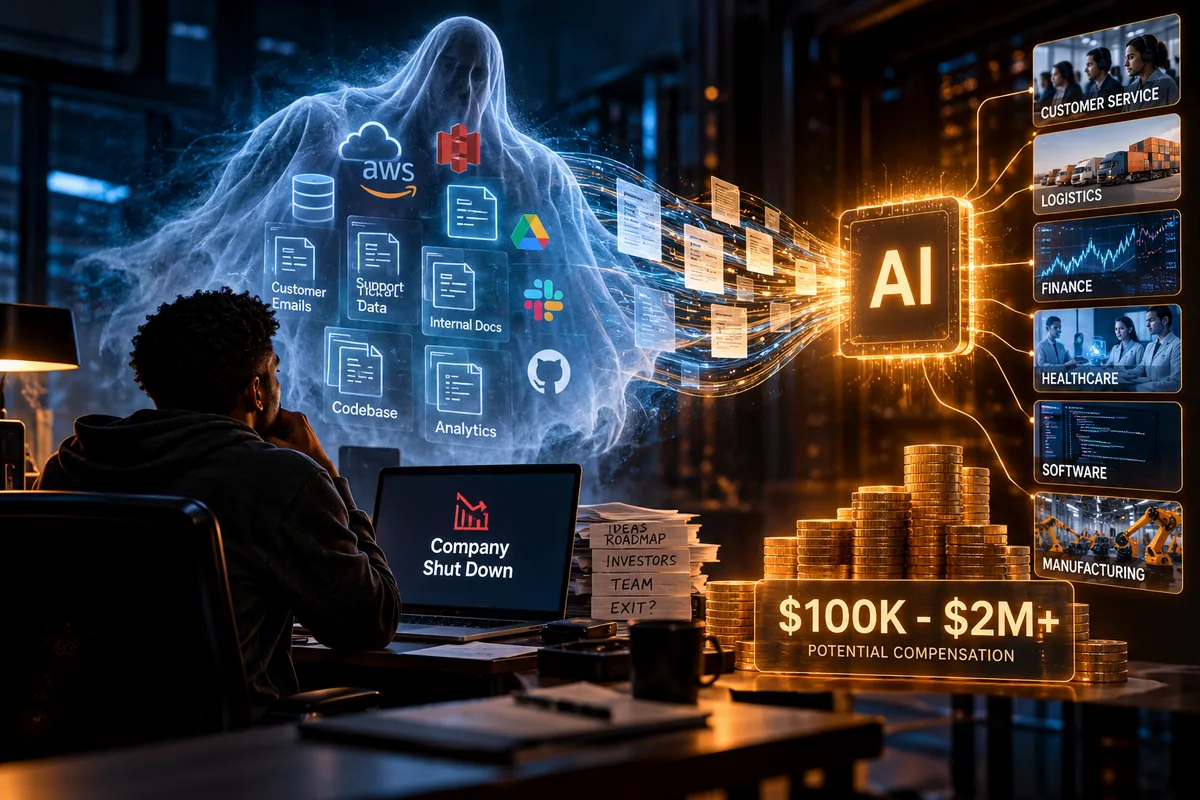
If you shut down a business over the last few years, there is a good chance you have a digital ghost following you around.
It might be an AWS S3 bucket you are still paying thirty dollars a month for, simply because clicking "Delete Bucket" feels too permanent. It might be a PostgreSQL dump sitting on an encrypted external drive in a desk drawer. It could be an export of thousands of customer support tickets, operational manuals, and proprietary internal workflows sitting in a cold Google Drive folder.
Every time that recurring credit card charge shows up on your bank statement, you feel a familiar pang in your chest. It is a quiet reminder of an enterprise that consumed your life, burned your savings, and ended before it was supposed to.
Most founders keep those archives around out of sentimentality or a faint hope that they might reuse a few lines of code one day. But they assume the business value of that archive is exactly zero.
They are usually wrong.
Why the Old Playbook Got It Wrong
When a company enters dissolution, founders are told that their assets fall into three narrow categories:
- Tangible equipment, like office monitors and computers.
- Registered intellectual property, like trademarks or granted patents.
- Active customer contracts with recurring revenue.
If you did not have a registered patent portfolio and your customers migrated elsewhere when you shut down, traditional brokers told you that your company was worth nothing. You were told to wipe the drives, settle what you could with creditors, and move on.
This advice was based on an outdated assumption: that software and business records are only valuable when coupled with an active, operating business.
In the pre-AI era, that was true. A competitor could not easily take your database schema or five years of internal operational logs and turn them into revenue without rebuilding your entire organization. To a traditional corporate buyer, raw historical data without active cash flow was a liability rather than an asset.
The emergence of enterprise artificial intelligence turned that entire logic upside down.
The Real Fuel of the AI Economy
Everyone knows that major technology companies and AI research labs are spending tens of billions of dollars on computing infrastructure. What is less talked about is their single biggest operational bottleneck: high-quality domain data.
Public web scraping has hit a wall. AI models trained exclusively on Wikipedia, Reddit, and public blogs already understand general language, but they fail when asked to solve complex, domain-specific business problems. To build intelligent systems for logistics, enterprise software, finance, customer service, and manufacturing, AI companies need to train their models on how real businesses actually function.
They need to see how real support teams resolved edge-case complaints over three years. They need to analyze how complex supply chain exceptions were documented and resolved. They need real codebases with five years of Git commit histories showing how systems evolved in response to operational pressure.
They cannot generate this synthetically with software, because synthetic data lacks the authentic edge cases and messy problem-solving that define real human business operations.
Your closed company generated precisely this type of data every single day it was alive.
What Actually Qualifies as Licensable Data?
Founders often assume that AI developers only want spotless, academic datasets or massive consumer social graphs. In reality, enterprise buyers look for operational depth across several distinct categories:
- Customer Interaction Logs: Large volumes of real conversations, ticket resolutions, and support transcripts that demonstrate human negotiation and troubleshooting.
- Technical and Engineering Records: Proprietary repositories, documentation libraries, architecture decision records, and operational runbooks.
- Domain-Specific Workflows: Structured records from specific verticals, such as legal paperwork pipelines, healthcare operational records, supply chain routing data, or real estate valuation histories.
- Business Operations History: Historical transactional logs, catalog records, inventory flow models, and specialized market interactions.
These assets do not become obsolete just because the entity that created them stopped trading. In fact, historical data from a defined multi-year operating period is often preferred because it represents a complete, closed cycle of real-world activity.
Clearing the Hurdles: Legal, Privacy, and Control
Monetizing historical company data is not as simple as dropping a zip file on a public marketplace. It requires careful navigation of rights, confidentiality, and ethics.
First, personal identifiable information (PII) must be thoroughly identified and handled. AI labs want the operational knowledge embedded in the records, not the private personal lives of individual consumers.
Second, legal authority matters. Whether your company is fully dissolved, wound down through an assignment, or sitting dormant as a legal entity, the authority to license its remaining assets must be verified. Who controls the rights? What did your original terms of service specify regarding data ownership and transfer?
Third, founders should never have to compromise their security. You should never be asked to upload raw, confidential databases to an unverified third party just to see if there is potential buyer interest. Preliminary evaluation should always begin with high-level descriptions of data categories, approximate volumes, and operational domain.
From Lingering Burden to Residual Asset
Select enterprise data acquisition programs currently advertise compensation packages ranging from $100,000 to over $2 million for qualifying, high-volume datasets.
While compensation is never guaranteed and every potential opportunity depends heavily on buyer appetite, data verification, and rights review, the opportunity is very real.
For founders who carried the heavy burden of a shutdown, exploring data licensing offers something rare: a second chance to extract return from years of uncompensated effort. It provides a pathway to pay down lingering debt, return capital, or simply close a difficult chapter of life on your own terms.
That digital ghost in your storage account does not have to stay a source of quiet frustration. It might be the most valuable thing your company ever produced.